WhoIsErykBench
Table of Contents
WhoIsErykBench and the Marginal Fact
I am an extremely minor internet figure, too obscure to even realistically be considered a "niche internet microcelebrity." But I do have a relatively wide body of work, between some stuff like the Melee Stats videos, SSBMRank, various pieces on this website, and so on.
Recently, I've been napkin testing language models by asking them if they remember anything about me, without using search tools. Part of this is because whether or not LLMs are listening is something I hold interest in. But the other part of this is that "knowledge of Eryk Banatt" is an extremely marginal fact. There are many hundreds of thousands, if not millions of figures more important to know about than myself. So it stands to reason that a model which knows about me probably knows a sizable portion of the people above me, also.
A remarkable thing about the current generation of models is that they are the first language models which seem to have clearly heard of me before. This seems to mostly be a function of size, rather than capability: models like Claude Opus 5.5 seem to have not heard of me, compared to "weaker" models like Claude Fable 5.1 having a much clearer idea. In this sense, knowing about me seems like a fun back-of-the-envelope test for "marginal facts," i.e. facts which exist at the fringe of current capability.
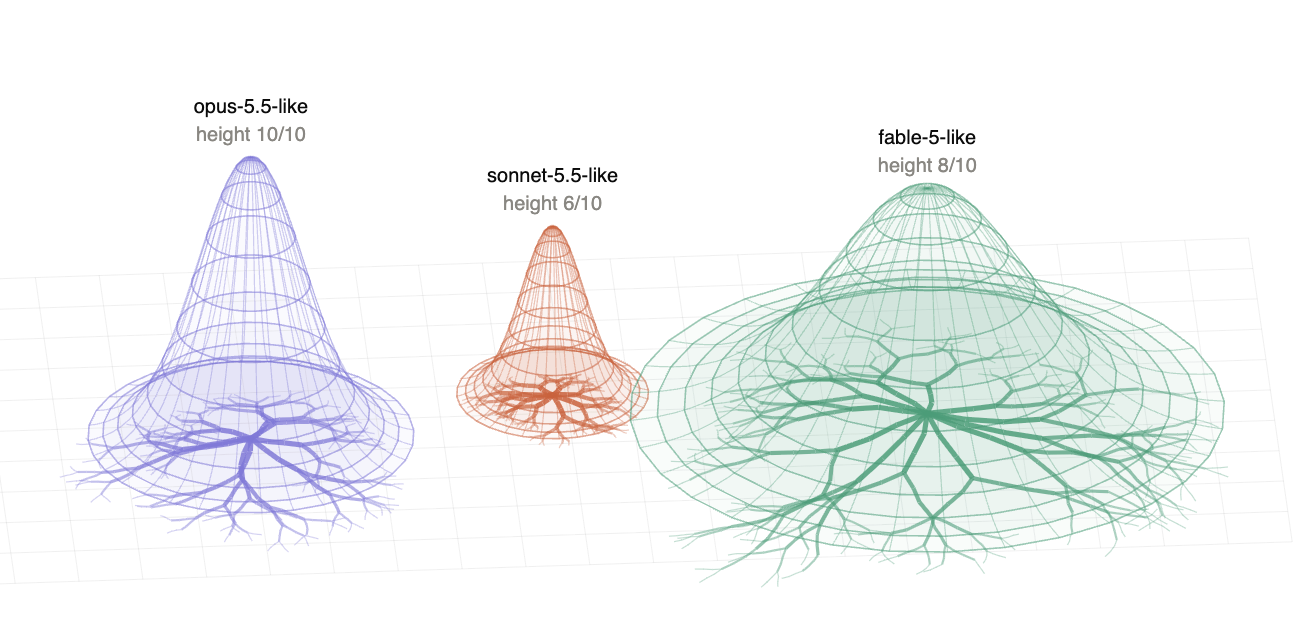
I like to think of this sort of information as being indicative of a model's "roots network" as if the model were a large tree. Some models have extremely wide base of facts (e.g. Fable 5.1, GPT-6 Astra) and others have a narrower base but grow taller in spite of it. This probably has some implications in the types of tasks these models are useful for, and it's probably easier to get value from LLMs if your prerequisite set of facts are less marginal.
Below is a little table of what the models say when prompted about me, and instructed to not use search tools. They generally fall into three categories: "Fuzzy Knowledge", "Near-Miss Knowledge", and "No Knowledge".
Fuzzy Knowledge4 models
Near-Miss Knowledge8 models
No Knowledge13 models
In general I'd say no model seems very confident about me yet, the way they would be about, say, Gwern Branwen. It is pretty interesting that this vaguely seems to correspond with model size more than anything else. There probably is some sort of fundamental information compression ceiling that would prevent something like this from being clearly recallable by something, for example, in the ~4B parameter range.
Some models are more willing to confuse me with stuff clearly nearby in the latent space. The gemini models, for example, will sometimes correctly identify my gamertag ("Ambisinister"), but will frequently confuse me with other people (e.g. attributing to me things done by PracticalTAS or Edwin Budding). A lot of these feel like wild swings which definitely seem to imply I'm somewhere in the training data, but not clearly enough to not get smashed in with other things.
Not fully sure what to do with this information. If nothing else, pretty good motivation to keep writing more.